See exactly where your delivery flow is waiting
Preview the phase-by-phase report for review pickup, active review, and merge time. Connect in about five minutes; the initial analysis runs after sync.
Read-only GitHub · Your code stays yours · Team-level by default · No credit card
"How fast are we shipping?" It's one of the most common questions engineering leaders face. But measuring engineering velocity incorrectly leads to gaming, burnout, and a false sense of productivity. This guide shows you how to measure velocity in ways that actually predict delivery success, and why story points per sprint are the wrong yardstick.
Velocity isn't about working faster - it's about sustainable, predictable delivery that improves over time. The right metrics help you identify obstacles, optimize flow, and demonstrate value to stakeholders. See our research on what separates elite engineering teams for the data behind these recommendations.
Velocity vs Speed: What's the Difference
Speed Is Not Velocity
In physics, speed is how fast you're moving. Velocity includes direction. The same distinction matters in engineering:
- Speed: How many lines of code, PRs, or tickets did we complete?
- Velocity: How much progress did we make toward our goals?
A team that ships 50 PRs but builds the wrong features has high speed and zero velocity. A team that ships 10 PRs that solve the customer's top problem has high velocity.
The Problem with Speed Metrics
When teams optimize for speed metrics, you see predictable dysfunction:
- PRs split artificially to increase count
- Easy tickets cherry-picked, hard problems avoided
- Quality sacrificed for throughput
- Technical debt accumulated faster than value
- Burnout from unsustainable pace
Sustainable Velocity
Real velocity is sustainable. A team that sprints for two weeks and crashes for two weeks has an average velocity of half their sprint capacity - and accumulates the debt from rushed work.
Sustainable velocity means a pace you can maintain indefinitely, with consistent output week over week.
Why Are Story Points a Poor Velocity Metric?
Story points were designed as a planning tool: a team estimates relative effort so it can forecast what fits in a sprint. They were never meant to compare teams or judge performance. Once a number is reported upward, predictable things happen:
- Teams inflate estimates to look faster, so the same work scores higher each quarter
- There is no standard unit - one team's 5 is another team's 13
- Pressure to "hit velocity" pushes people to skip reviews and tests
- The number says nothing about whether anything reached customers
Keep story points for what they are good at, forecasting inside one team (see our sprint velocity guide and forecasting without estimates). To measure how fast work is actually delivered, use signals taken from merged and deployed work: the metrics below.
The Velocity Metrics That Actually Matter
Cycle Time
What it measures: Time from first commit to production deployment.
Cycle time is the single most important velocity metric. It measures how quickly you can turn an idea into customer value. Shorter cycle times mean:
- Faster feedback loops
- Smaller batches of work (lower risk)
- More experiments possible
- Quicker response to customer needs
Learn how to break this down and improve it in our cycle time breakdown guide.
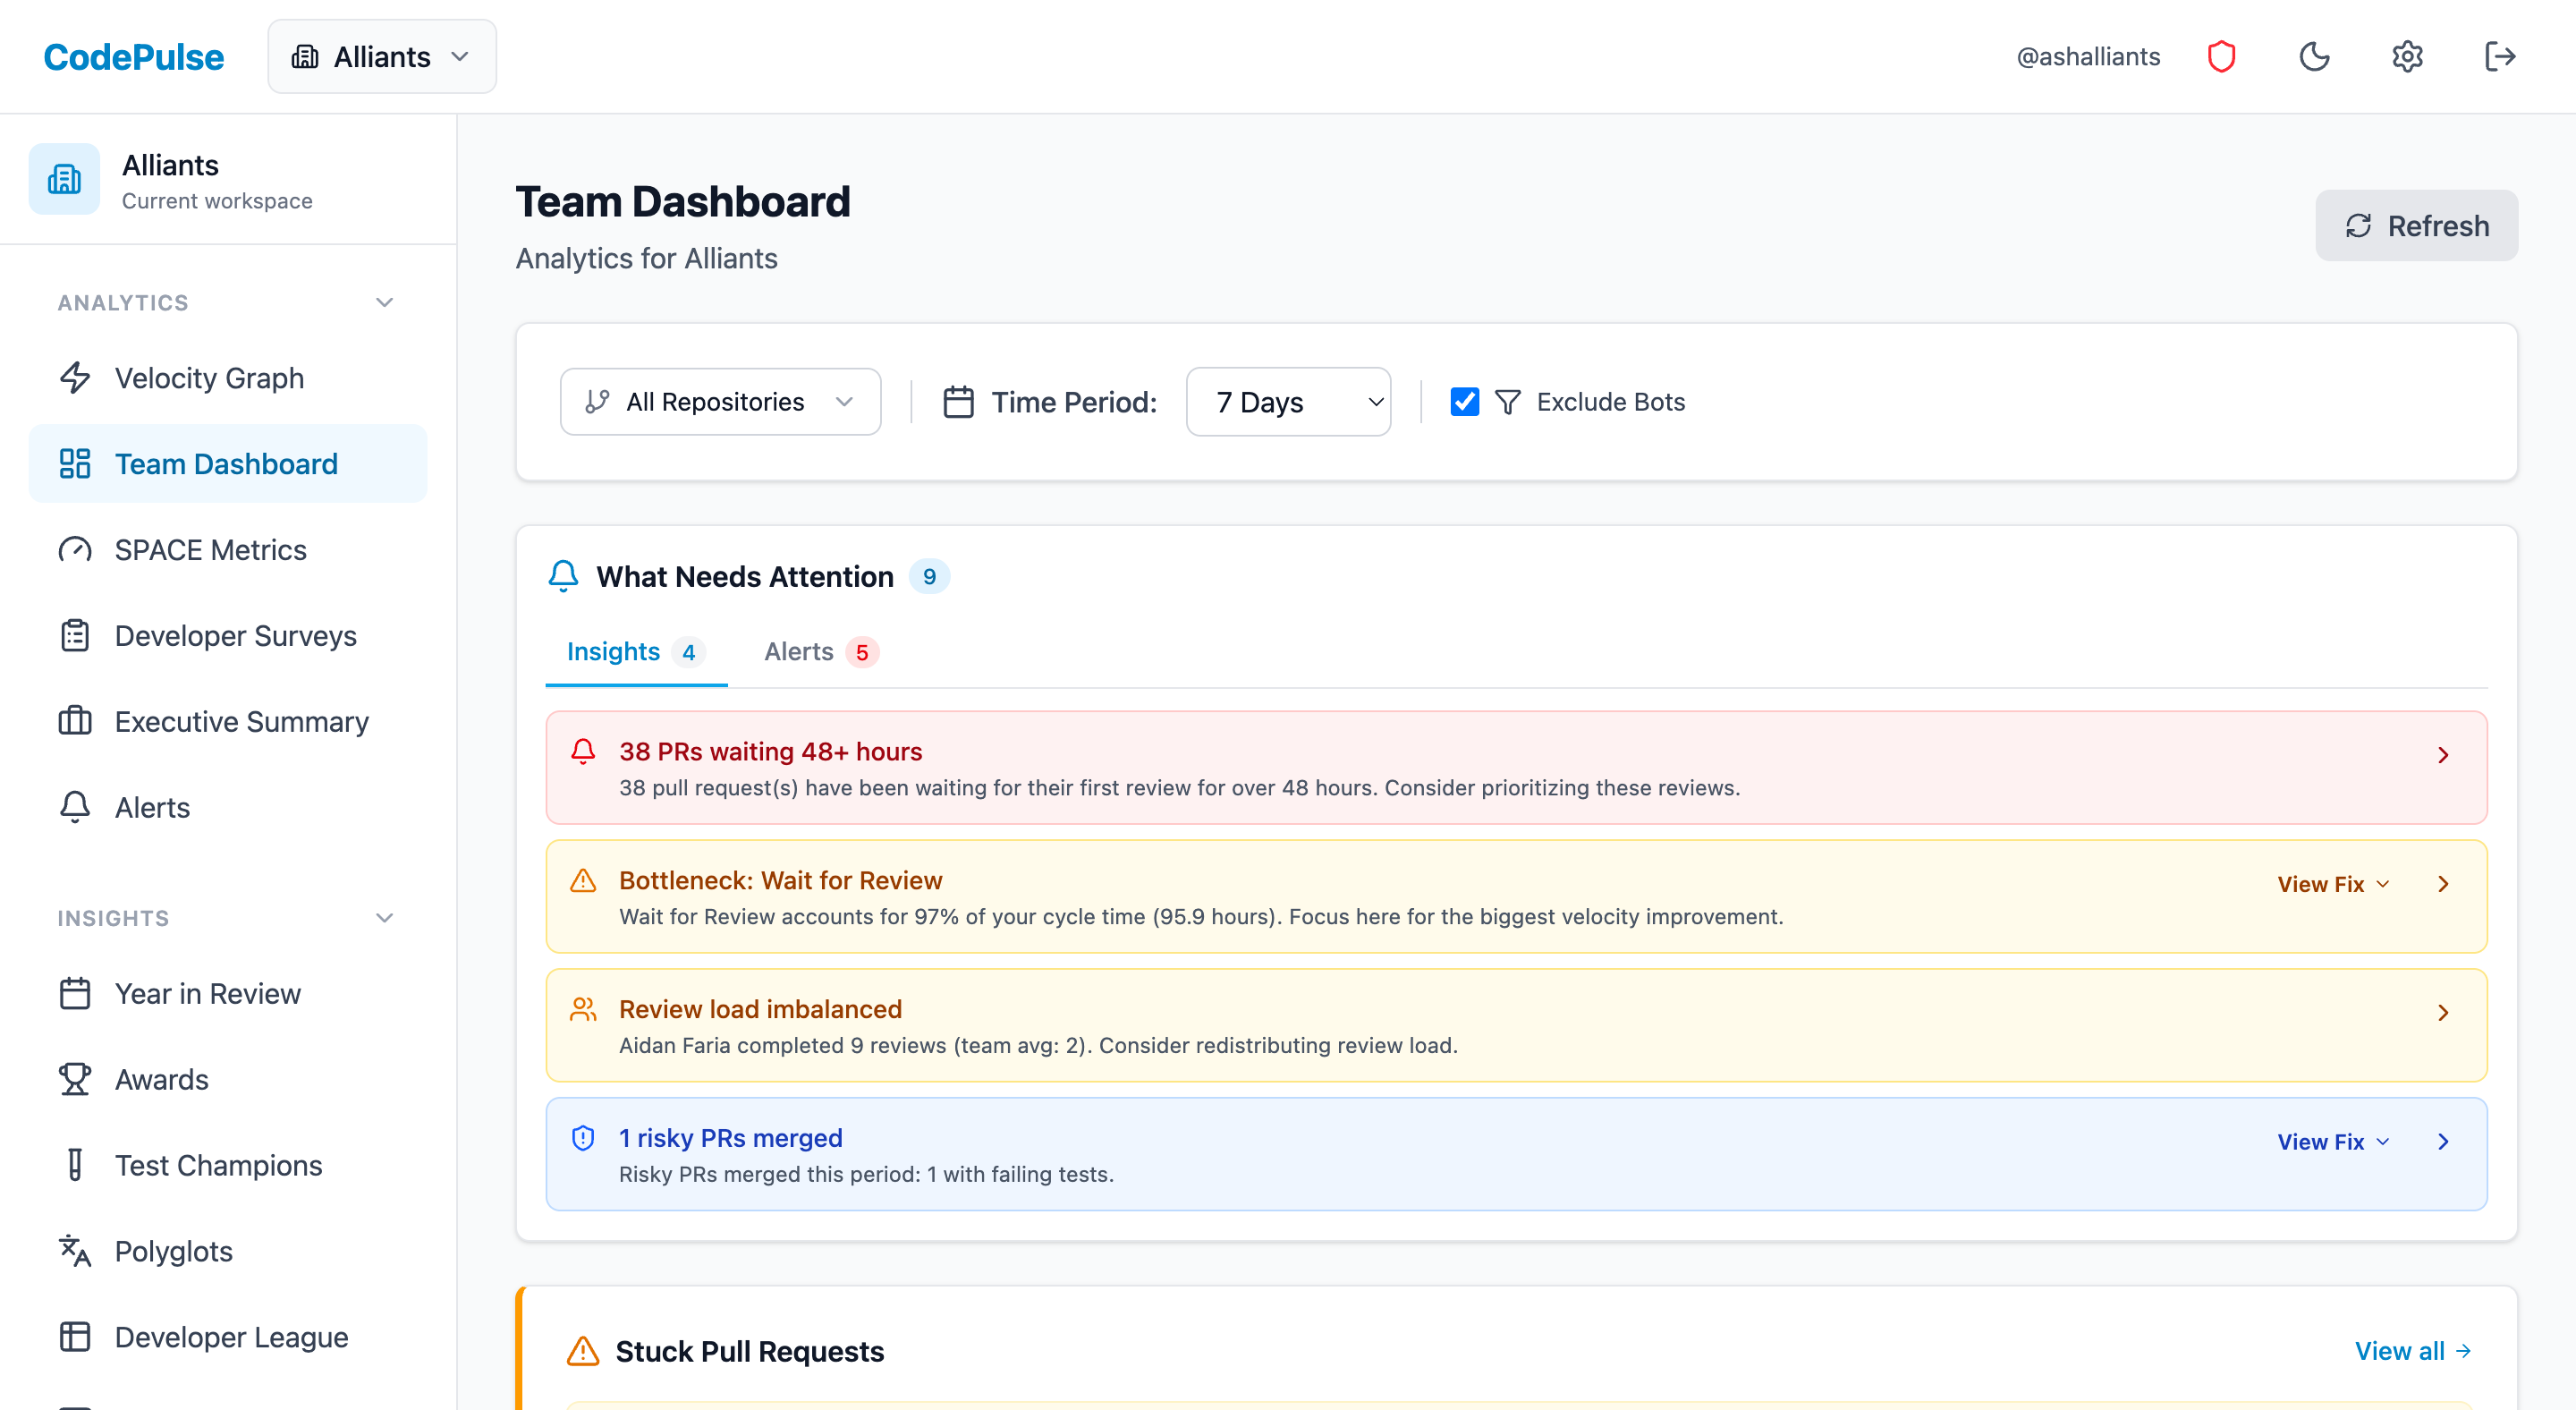
📊 How to See This in CodePulse
Navigate to Dashboard to see your cycle time breakdown:
- Total cycle time with trend over time
- Breakdown into coding, review wait, review, and merge phases
- Filter by repository or team to find bottlenecks
Deployment Frequency
What it measures: How often you release to production.
Deployment frequency is a key indicator of delivery capability. Teams that deploy more often tend to:
- Ship smaller, safer changes
- Find problems faster
- Respond to customer needs quickly
- Have more mature CI/CD practices
| Frequency | Typical level |
|---|---|
| On demand (multiple per day) | Strong |
| Daily to weekly | Good |
| Weekly to monthly | Fair |
| Monthly to quarterly | Needs work |
See our deployment frequency guide for improvement strategies.
PR Throughput
What it measures: PRs merged per time period (team-level).
PR throughput is useful as a relative measure - comparing a team against its own history. An increasing trend suggests improving efficiency. A declining trend might indicate:
- Growing complexity in the codebase
- Review bottlenecks
- Scope creep in work items
- Team focus shifting to other activities
Caution: Don't compare throughput across teams or use as individual metrics - PR size and complexity vary too much.
Flow Efficiency
What it measures: Active work time divided by total elapsed time.
Flow efficiency reveals how much of your cycle time is actual work versus waiting. A PR that takes 5 days but only has 4 hours of coding and 1 hour of review has flow efficiency of about 10%.
Typical flow efficiency ranges:
- 5-15%: Common but indicates significant waste
- 15-40%: Good range for most teams
- 40%+: Excellent, approaching optimal
Low flow efficiency usually indicates waiting - for reviews, dependencies, or decisions.
Sustainable Pace vs Burnout Sprint
Recognizing Unsustainable Velocity
High velocity metrics can mask unsustainable practices. Warning signs:
- After-hours activity: Commits clustering late nights and weekends
- Accelerating churn: More code being rewritten shortly after shipping
- Declining review quality: Fewer comments, faster approvals
- Growing PR sizes: Batching work instead of flowing it
- Rising cycle time variability: Some PRs fast, others stuck for days
Learn more about identifying these patterns in our burnout signals guide.
The Productivity J-Curve
When you push for higher velocity, short-term output often increases while long-term productivity decreases - a J-curve pattern:
- Week 1-2: Velocity spikes as people work harder
- Week 3-4: Quality issues emerge, some rework needed
- Week 5+: Technical debt compounds, velocity crashes below baseline
Sustainable velocity avoids this trap by maintaining consistent quality standards.
DORA Metrics and Velocity Connection
The Five DORA Metrics
DORA, the research program behind the State of DevOps reports, now tracks five software delivery metrics, split into two groups:
Throughput
- Change Lead Time: How long a change takes to go from committed to version control to deployed in production
- Deployment Frequency: How often you deploy, or the time between deployments
- Failed Deployment Recovery Time: How long it takes to recover from a deployment that fails and needs immediate intervention
Instability
- Change Fail Rate: The ratio of deployments that need immediate intervention after release
- Deployment Rework Rate: The ratio of deployments that are unplanned and happen because of a production incident
The throughput metrics are the delivery-speed side of velocity. The instability metrics show whether that speed is being paid for with failures. DORA's research has long found that speed and stability tend to rise together instead of trading off, which is why velocity goals should always carry a stability counterweight.
Deep dive into these in our complete DORA metrics guide.
Why Velocity Without Stability Fails
Teams that optimize only for velocity often see rising change failure rates. Each incident creates unplanned work that reduces future velocity. The fastest sustainable pace is one that keeps change fail rate and rework low. A balanced goal reads like "cut cycle time by 20% while change fail rate stays flat", not "increase velocity by 20%".
Improving Velocity Without Adding Headcount
Reduce Wait Time
Most cycle time is waiting, not working. Target:
- Review wait time: Set review SLAs, balance reviewer load. See our review load balancing guide.
- CI/CD time: Parallelize tests, optimize build pipelines
- Decision latency: Empower teams to make decisions without escalation
- Dependency wait: Reduce coupling between teams
Reduce Batch Size
Smaller batches flow faster through the system:
- Smaller PRs get reviewed and merged faster
- Smaller deployments are safer and easier to debug
- Smaller features deliver value incrementally
See our PR size optimization guide.
Reduce Rework
Every bug found in production, every PR revision, every unclear requirement creates rework. Invest in:
- Better requirements clarity upfront
- Automated testing to catch bugs early
- Code review quality to prevent defects
- Documentation to reduce misunderstandings
Reduce Context Switching
Each interruption costs 20+ minutes of recovery time. Help developers focus:
- Batch meetings to preserve focus blocks
- Asynchronous communication as default
- Clear ownership to reduce cross-team pings
- Automated alerts instead of manual status checks
Explore this in our context switching guide.
Limit Work in Progress
Every extra item a developer juggles adds context-switching cost, and the work all finishes later. Finishing one PR before starting the next is almost always faster than making a little progress on five. Watch open PRs per developer and the age of your oldest open PR: if both grow, velocity is leaking into queues.
Setting Realistic Velocity Targets
Baseline First
Before setting targets, establish your current state:
- What's your current cycle time distribution?
- How frequently are you deploying?
- What's your flow efficiency?
- How much variability exists week-to-week?
Rough Working Targets
These are rule-of-thumb targets, not official DORA bands: DORA's 2025 report describes seven team profiles instead of fixed Elite/High/Medium/Low tiers. Use them to sanity-check your baseline, then track your own trend.
| Metric | Solid | Strong |
|---|---|---|
| Cycle time | <1 week | <1 day |
| Deployment frequency | Weekly | On demand |
| Flow efficiency | >15% | >40% |
See our PR cycle time benchmarks for detailed comparisons.
Improvement Targets
Rather than targeting absolute numbers, target improvement rates:
- "Reduce cycle time by 20% this quarter"
- "Increase deployment frequency by 50% over 6 months"
- "Reduce review wait time to under 24 hours"
Improvement targets are more motivating than arbitrary benchmarks, and they account for your team's starting point.
How Do You Measure Software Development Velocity for Enterprise Engineering Teams?
At enterprise scale, "measure velocity" usually means someone wants a single number to roll up across dozens of teams. Resist that urge. Velocity is a system-level signal, not a per-team target, and treating it as a target at scale multiplies the failure modes above across every team that reports into a dashboard.
The safer approach is to measure aggregate flow health across the organization: cycle time distribution by team, deployment frequency trends, and flow efficiency, then look for outliers rather than ranking teams against each other. A team with unusually high output isn't necessarily the model to copy; it can be a warning sign. Our guide on high activity without progress covers how heavy commit and PR volume can coexist with stalled delivery, which is exactly what a raw velocity number hides.
For enterprise planning, forecasting from historical flow data is more reliable than asking every team to estimate story points against a velocity target. See our guide on forecasting instead of estimating for how to use throughput data for capacity planning without turning velocity into a KPI teams learn to game. The goal at any scale is the same: velocity should describe what happened, never dictate what must happen next.
💡 Remember
Velocity should improve quality of life, not degrade it. If improving velocity makes engineers miserable, you're doing it wrong. The goal is sustainable delivery that makes work better for everyone - developers, managers, and customers.
Frequently Asked Questions
Measure at the team level using percentile-based benchmarks rather than averages or individual rankings. Track each team's cycle time distribution (p50 and p85), deployment frequency, and flow efficiency, then compare against benchmarks for similar team sizes instead of ranking teams against each other - averages hide the stuck PRs that actually delay releases. Segment by team, never by individual: individual velocity metrics invite gaming and say nothing about system health. Use the resulting throughput history for forecasting and capacity planning rather than as a target, so velocity describes what happened instead of dictating what must happen next.
Find out which phase is holding your delivery up
CodePulse splits your cycle time into coding, waiting for review, active review, and merge, so you fix the queue that is actually costing you days. Read-only GitHub, no credit card.
Read-only GitHub · Your code stays yours · Team-level by default · No credit card
See These Features in Action
Break down cycle time into coding, waiting, review, and merge phases.
Track all four DORA metrics and benchmark against industry standards.
Related Guides
DORA Metrics Explained: The 4 Keys Without the Hype
A complete breakdown of the four DORA metrics - deployment frequency, lead time, change failure rate, and MTTR - with honest benchmarks and gaming traps to avoid.
Measure Deploy Frequency Without CI/CD (The Hack)
Master DORA deployment frequency and lead time using GitHub data alone, without requiring CI/CD pipeline access.
Your PR Cycle Time Is Fine (Here's the Benchmark)
What is a good PR cycle time? Benchmarks and targets based on team size, industry, and engineering maturity.
We Cut PR Cycle Time by 47%. Here's the Exact Playbook
A practical playbook for engineering managers to identify bottlenecks, improve review processes, and ship code faster - without sacrificing review quality.
Your Best Engineer Is About to Quit (Check Review Load)
Learn how to identify overloaded reviewers, distribute review work equitably, and maintain review quality without burning out your senior engineers.
DevOps Maturity Model: A Practical Assessment Framework
Assess your DevOps maturity across culture, CI/CD, testing, monitoring, and infrastructure. Includes self-assessment questionnaire and improvement roadmap by level.
Sprint Velocity: What It Is and How to Use It
A plain-English guide to sprint velocity in Scrum: what it measures, how to calculate it, and why it fails the moment you treat it as a productivity metric.
Story Points Are a Scam. Here's What Actually Works
Story points are often waste. Learn how to use historical throughput and cycle time to forecast delivery dates with higher accuracy and less meeting time.