# We Built Our Own Analytics. Here's Why We Switched to SaaS
> We built analytics from GitHub API. Here's why we switched to SaaS-and when DIY actually makes sense.
#### Compare the finished analysis before you choose a platform
See the report CodePulse produces from read-only GitHub workflow data, or connect your own repositories and evaluate the fit with real evidence.
[Analyze My GitHub Data](https://codepulsehq.com/signup) · [Preview the Sample Report](https://codepulsehq.com/sample-report) · [Explore the live demo](https://codepulsehq.com/demo) Read-only GitHub · Your code stays yours · Team-level by default · No credit card
For platform engineers and staff developers, the idea of treating engineering analytics like infrastructure - version-controlled, automated, and programmatic - is appealing. This guide explores the "analytics as code" approach: building your own metrics pipeline from GitHub data, when it makes sense, and when you should buy instead of build.
Should you build or buy engineering analytics?
Build if you have unique requirements that no SaaS tool covers, a dedicated platform team with spare capacity, and the willingness to maintain the pipeline long-term. Buy if you want insights within a week, lack platform engineering resources, or would rather spend engineering time on your product. Most teams underestimate maintenance costs: a custom analytics pipeline requires ongoing work as GitHub APIs change, data models evolve, and new metrics are needed. CodePulse provides a ready-made analytics layer with a 5-minute setup that covers the metrics most teams need.
We'll cover the technical approach, including code examples for the GitHub API, along with the hidden complexity that makes DIY analytics harder than it first appears.
## What Is Analytics as Code
### The Philosophy
"Analytics as code" applies infrastructure-as-code principles to engineering metrics:
- **Version controlled:** Metric definitions live in Git, not UI configs
- **Automated:** Data collection runs in pipelines, not manual exports
- **Reproducible:** Anyone can understand how metrics are calculated
- **Extensible:** Adding new metrics follows standard development workflow
### The Appeal for Technical Teams
For staff engineers and platform teams, building your own analytics has appeal:
```
Why engineers want to build:
Control:
"We can measure exactly what we care about"
"No vendor lock-in"
"Customize to our specific workflow"
Integration:
"Embed metrics in our developer portal"
"Connect to our existing data warehouse"
"Use our own visualization tools"
Cost:
"GitHub API is free"
"We have the skills in-house"
"Avoid per-seat SaaS pricing"
Learning:
"Our team will understand it deeply"
"Good project for platform engineers"
```
See where your delivery slows down, and why. [Analyze your own data](https://codepulsehq.com/signup)
## The DIY Approach: GitHub API + Your Pipeline
### GitHub API Basics
GitHub provides both REST and GraphQL APIs for accessing repository data. For analytics, GraphQL is generally more efficient because you can fetch exactly the fields you need in fewer requests.
#### Authentication
```
# Personal Access Token (for development/small scale)
curl -H "Authorization: token YOUR_PAT" \
https://api.github.com/repos/owner/repo/pulls
# GitHub App (for production/organization-wide)
# 1. Create GitHub App
# 2. Install on organization
# 3. Generate installation access token
# 4. Use token for API calls (expires after 1 hour)
```
#### Fetching Pull Request Data (REST)
```
import requests
from datetime import datetime, timedelta
def get_merged_prs(owner, repo, token, since_days=30):
"""Fetch PRs merged in the last N days."""
headers = {
"Authorization": f"token {token}",
"Accept": "application/vnd.github.v3+json"
}
since = datetime.now() - timedelta(days=since_days)
prs = []
page = 1
while True:
response = requests.get(
f"https://api.github.com/repos/{owner}/{repo}/pulls",
headers=headers,
params={
"state": "closed",
"sort": "updated",
"direction": "desc",
"per_page": 100,
"page": page
}
)
response.raise_for_status()
page_prs = response.json()
if not page_prs:
break
for pr in page_prs:
if pr.get("merged_at"):
merged_at = datetime.fromisoformat(
pr["merged_at"].replace("Z", "+00:00")
)
if merged_at >= since.replace(tzinfo=merged_at.tzinfo):
prs.append(pr)
else:
# PRs are sorted by updated, so we might
# need to continue for older merges
pass
page += 1
# Basic rate limit check
remaining = int(response.headers.get("X-RateLimit-Remaining", 0))
if remaining < 10:
break # Stop before hitting limit
return prs
```
#### Fetching with GraphQL (More Efficient)
```
import requests
QUERY = """
query($owner: String!, $repo: String!, $cursor: String) {
repository(owner: $owner, name: $repo) {
pullRequests(
first: 100
states: [MERGED]
orderBy: {field: UPDATED_AT, direction: DESC}
after: $cursor
) {
pageInfo {
hasNextPage
endCursor
}
nodes {
number
title
createdAt
mergedAt
additions
deletions
changedFiles
author {
login
}
reviews(first: 10) {
nodes {
author { login }
state
submittedAt
}
}
}
}
}
}
"""
def fetch_prs_graphql(owner, repo, token):
"""Fetch PRs with review data in single query."""
headers = {
"Authorization": f"bearer {token}",
"Content-Type": "application/json"
}
all_prs = []
cursor = None
while True:
response = requests.post(
"https://api.github.com/graphql",
headers=headers,
json={
"query": QUERY,
"variables": {
"owner": owner,
"repo": repo,
"cursor": cursor
}
}
)
data = response.json()
if "errors" in data:
raise Exception(f"GraphQL errors: {data['errors']}")
prs = data["data"]["repository"]["pullRequests"]
all_prs.extend(prs["nodes"])
if not prs["pageInfo"]["hasNextPage"]:
break
cursor = prs["pageInfo"]["endCursor"]
return all_prs
```
#### Calculating Cycle Time
```
from datetime import datetime
from statistics import median
def calculate_cycle_time(prs):
"""Calculate median cycle time from PR data."""
cycle_times = []
for pr in prs:
created = datetime.fromisoformat(
pr["createdAt"].replace("Z", "+00:00")
)
merged = datetime.fromisoformat(
pr["mergedAt"].replace("Z", "+00:00")
)
# Cycle time in hours
hours = (merged - created).total_seconds() / 3600
cycle_times.append(hours)
if not cycle_times:
return None
return {
"median_hours": median(cycle_times),
"min_hours": min(cycle_times),
"max_hours": max(cycle_times),
"count": len(cycle_times)
}
# Usage
prs = fetch_prs_graphql("myorg", "myrepo", token)
metrics = calculate_cycle_time(prs)
print(f"Median cycle time: {metrics['median_hours']:.1f} hours")
```
## Hidden Complexity: Rate Limits, Data Quality, Maintenance
### Rate Limit Challenges
GitHub's API has strict rate limits that complicate production use. Before you commit to a pipeline, our free [GitHub Organization Analyzer](https://codepulsehq.com/tools/github-org-analyzer) scans a whole org's repositories so you can see the data volume you'd be pulling:
```
GitHub API Rate Limits:
REST API:
- 5,000 requests/hour (authenticated)
- Pagination required for large result sets
- Each page = 1 request
GraphQL API:
- Point-based system (not simple request count)
- Complex queries cost more points
- 5,000 points/hour
Real-world impact:
- 50 repos × 100 PRs each = 5,000+ requests
- Fetching reviews, comments, files = more requests
- Historical backfill can take days
- Incremental sync required for production
```
#### Rate Limit Handling Code
```
import time
def handle_rate_limit(response):
"""Check rate limits and wait if needed."""
remaining = int(response.headers.get("X-RateLimit-Remaining", 0))
reset_time = int(response.headers.get("X-RateLimit-Reset", 0))
if remaining < 100:
wait_seconds = max(reset_time - time.time(), 0) + 10
print(f"Rate limit low. Waiting {wait_seconds}s...")
time.sleep(wait_seconds)
if response.status_code == 403:
# Secondary rate limit hit
retry_after = int(response.headers.get("Retry-After", 60))
print(f"Secondary rate limit. Waiting {retry_after}s...")
time.sleep(retry_after)
```
### Data Quality Issues
Raw GitHub data requires significant cleaning:
- **Bot commits:** Dependabot, Renovate, GitHub Actions pollute metrics
- **Force pushes:** Can lose commit history
- **Squash merges:** Hide individual commit timestamps
- **Timezones:** All times are UTC, working hours vary
- **Deleted branches:** Reference data may be missing
```
# Bot detection
BOT_PATTERNS = [
"[bot]",
"dependabot",
"renovate",
"github-actions",
"greenkeeper",
]
def is_bot(username):
"""Detect bot accounts."""
if not username:
return True
username_lower = username.lower()
return any(pattern in username_lower for pattern in BOT_PATTERNS)
# Filter PRs
human_prs = [pr for pr in prs if not is_bot(pr["author"]["login"])]
```
### Maintenance Burden
Building is just the start. Ongoing maintenance includes:
- API changes and deprecations
- Schema updates when GitHub adds fields
- Handling new edge cases as repos evolve
- Performance optimization as data grows
- Dashboard maintenance and feature requests
- On-call for data pipeline failures
Identify bottlenecks slowing your team. [Analyze your own data](https://codepulsehq.com/signup)
## When to Build vs Buy
### Build When:
- **Unique requirements:** You need metrics no vendor provides
- **Deep integration:** Metrics must embed in custom internal tools
- **Learning opportunity:** Building is a valuable platform team project
- **Small scale:** Just a few repos, simple metrics
- **Air-gapped:** No ability to use SaaS products
### Buy When:
- **Time-to-value:** You need insights now, not in 6 months
- **Scale:** Many repos, teams, or organizations
- **Standard metrics:** DORA, cycle time, review coverage
- **Limited platform capacity:** Team should focus on core product
- **Enterprise features:** SSO, audit logs, support SLAs
```
Build vs Buy Calculation:
DIY costs:
- Initial build: 2-3 engineers × 2-3 months = 4-9 eng-months
- Ongoing maintenance: 0.25-0.5 engineer ongoing
- Opportunity cost: What else could that time produce?
SaaS costs:
- $X per seat per month
- Implementation: days, not months
- Maintenance: vendor handles it
Break-even analysis:
Engineering cost: $150K/year fully loaded
9 eng-months = ~$112K initial investment
0.5 engineer ongoing = $75K/year
vs.
SaaS at $50/seat/month × 50 engineers = $30K/year
DIY break-even: 3+ years (if no maintenance growth)
Reality: DIY usually costs more than expected
```
## Using APIs for Custom Dashboards
### Hybrid Approach
You don't have to choose all-or-nothing. Many teams use a platform for data collection and core metrics, then build custom dashboards on top:
- **Use platform API:** Pull aggregated metrics programmatically
- **Embed in portal:** Display in your internal developer portal
- **Custom visualizations:** Build team-specific views
- **Integrate with other data:** Join with incident, OKR, or product data
```
# Example: Embed metrics in internal portal
# Fetch from platform API (hypothetical)
def get_team_metrics(team_id, period="weekly"):
response = requests.get(
f"https://api.yourplatform.com/v1/teams/{team_id}/metrics",
headers={"Authorization": f"Bearer {API_KEY}"},
params={"period": period}
)
return response.json()
# Display in your portal
metrics = get_team_metrics("platform-team")
print(f"""
Team Dashboard:
Cycle Time: {metrics['cycle_time_hours']:.1f} hours
Deployment Frequency: {metrics['deploy_frequency_per_week']:.1f}/week
Change Failure Rate: {metrics['cfr_percent']:.1f}%
""")
```
## Embedding Metrics in Developer Portals
### Backstage Integration Example
If you use Backstage or a similar developer portal, you can embed engineering metrics as a plugin or widget:
```
// Backstage plugin component (simplified)
import React, { useEffect, useState } from 'react';
import { useApi } from '@backstage/core-plugin-api';
export const TeamMetricsCard = ({ teamId }) => {
const [metrics, setMetrics] = useState(null);
useEffect(() => {
fetch(`/api/metrics/teams/${teamId}`)
.then(res => res.json())
.then(setMetrics);
}, [teamId]);
if (!metrics) return ;
return (
);
};
```
#### 📊 CodePulse API Access
CodePulse handles the complexity of GitHub data collection while providing API access for custom integrations:
- Pre-calculated DORA metrics and cycle time data
- Bot filtering and data quality built in
- Export to CSV for custom analysis
- [Export guide](https://codepulsehq.com/guides/export-engineering-metrics-csv) - Get your data in the format you need
#### 💡 Start Simple
If you're drawn to the analytics-as-code approach, start with a simple proof of concept: one metric, one repo, one week of data. You'll quickly discover the edge cases and maintenance burden. Then decide if the investment makes sense for your team.
## Frequently Asked Questions
Buy if you want insights within a week, lack a dedicated platform team, or need standard metrics like DORA and cycle time. Build if you have unique requirements no vendor covers and a team willing to maintain the pipeline long-term. Most organizations underestimate maintenance costs by 2-3x.
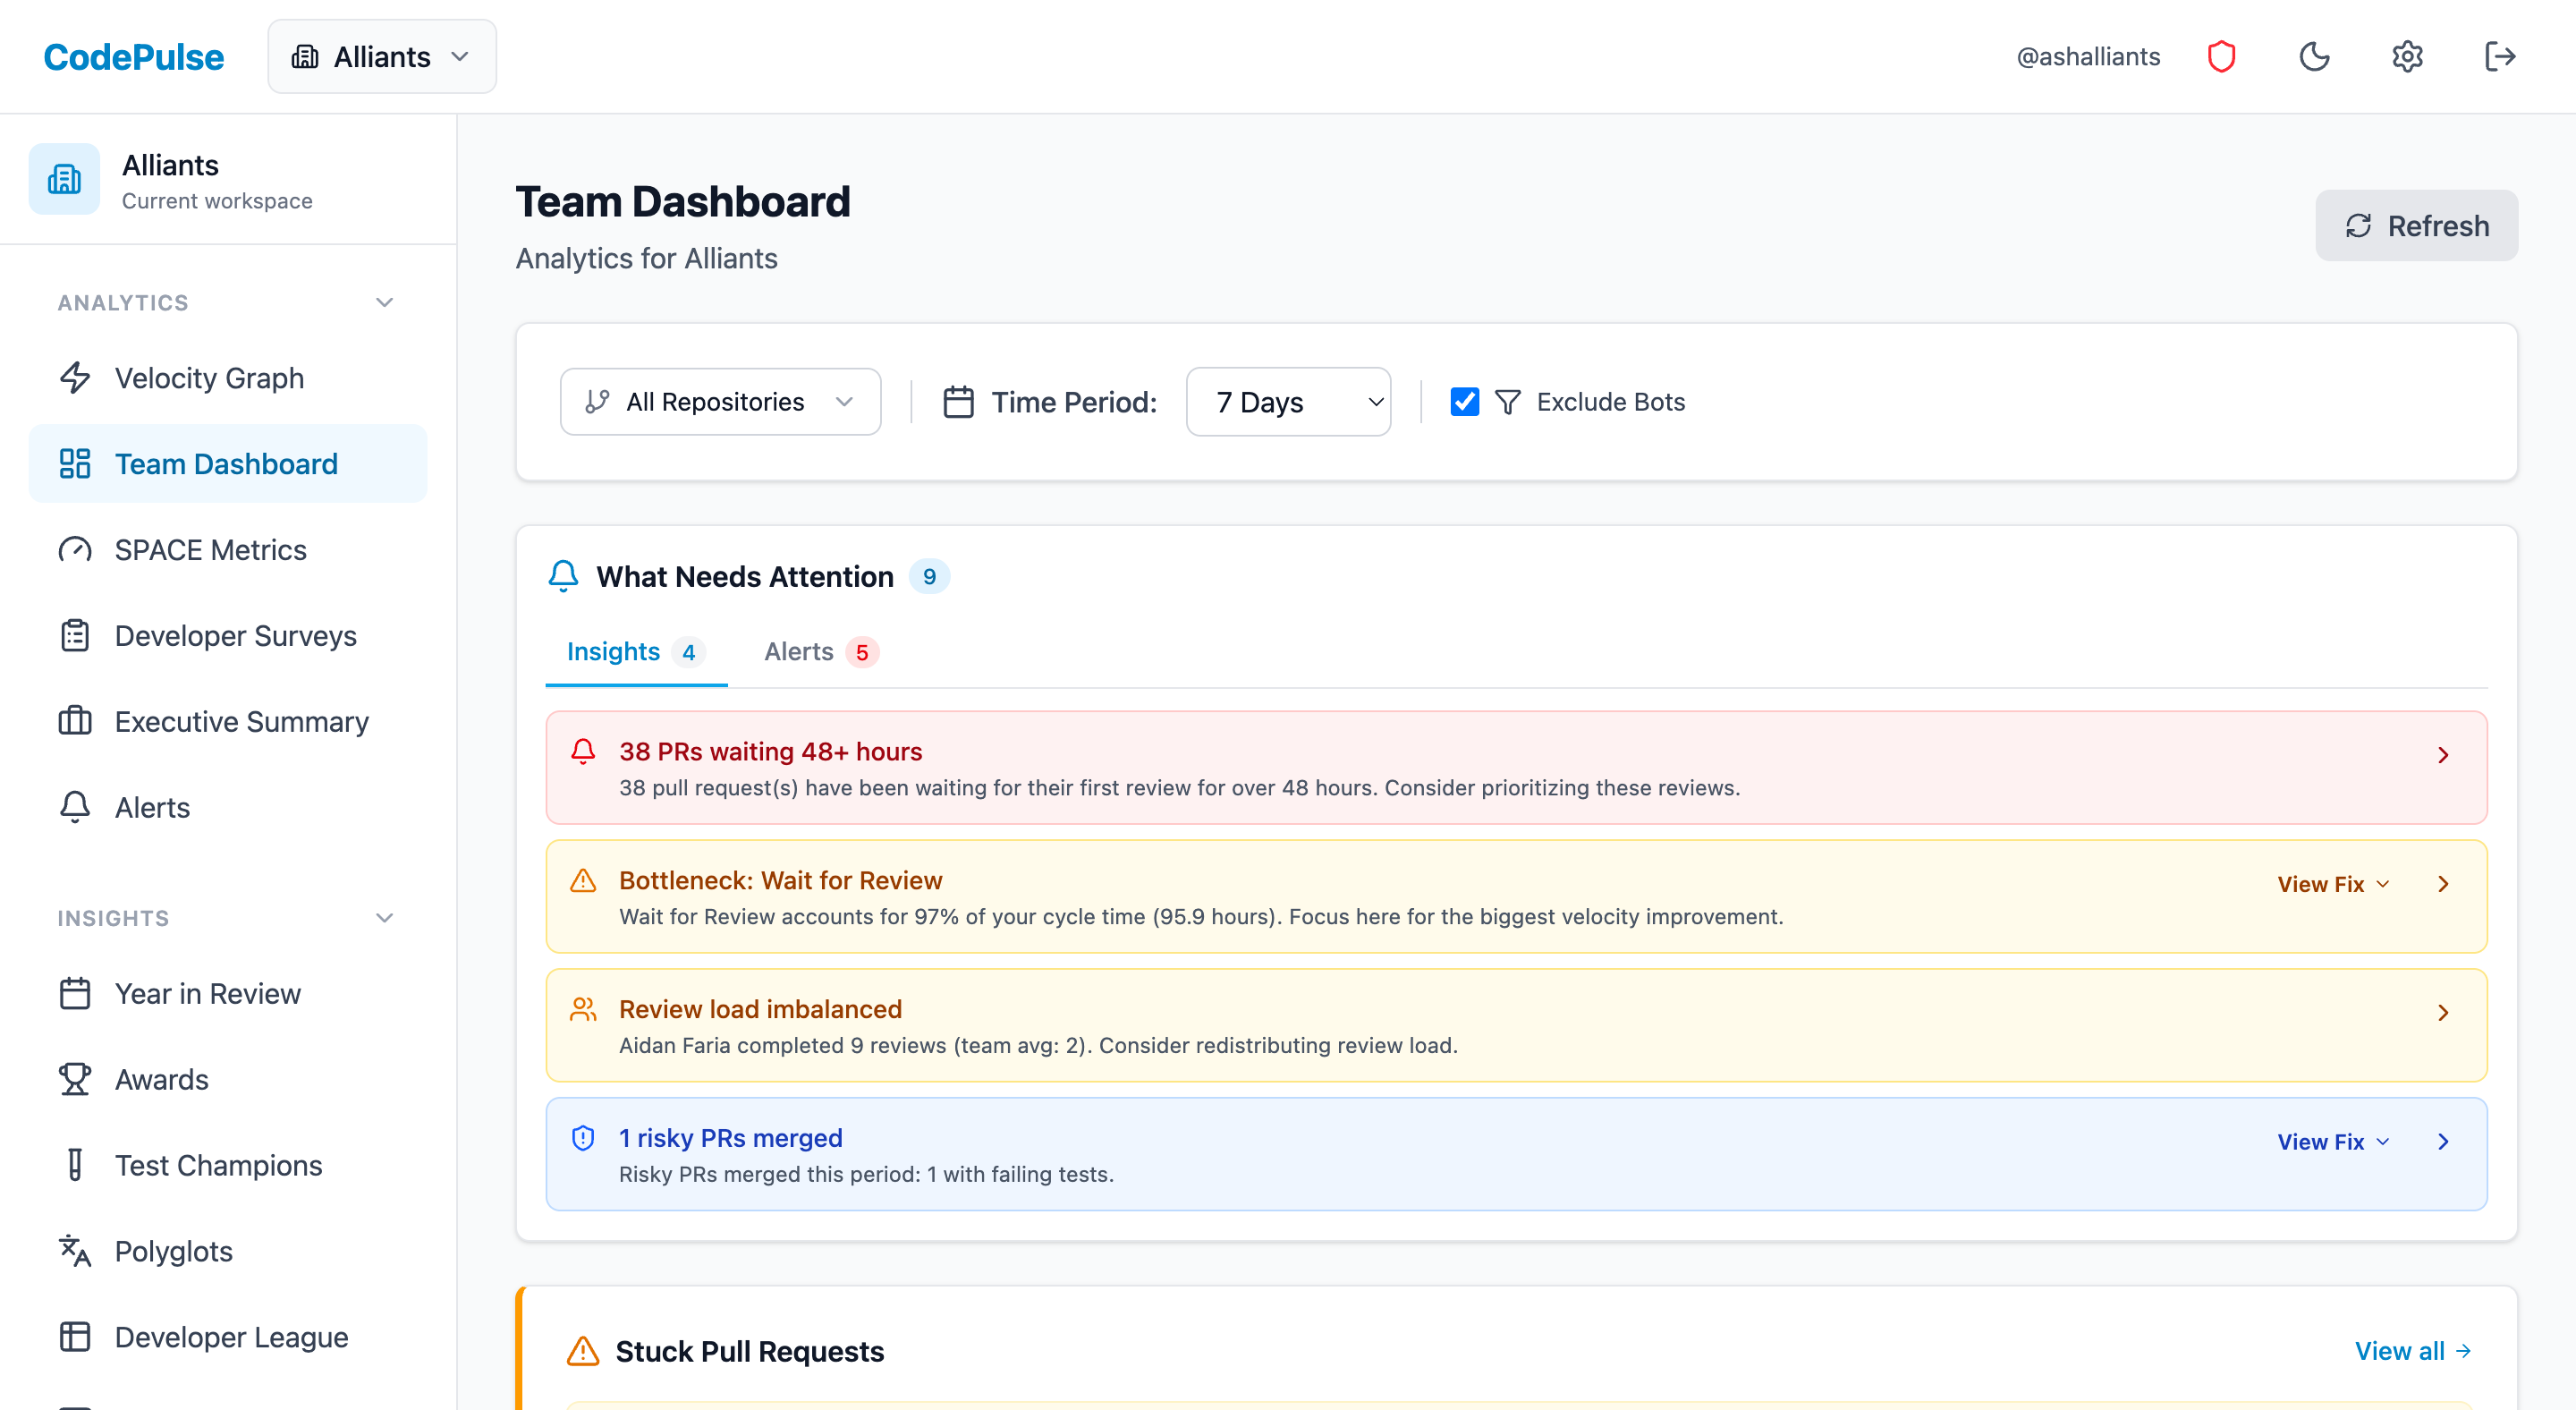
### Evaluate CodePulse against your own delivery history
A comparison table only goes so far. Connect read-only GitHub in about five minutes and judge the output on your repositories, at one flat price, with no per-seat math.
[Preview the Sample Report](https://codepulsehq.com/sample-report) [Explore the live demo](https://codepulsehq.com/demo) Read-only GitHub · Your code stays yours · Team-level by default · No credit card
### See These Features in Action
[Explore all features](https://codepulsehq.com/features)
## Related Guides
---
**About CodePulse:** CodePulse is a GitHub-native engineering analytics platform for engineering leaders managing teams of 50 to 500 developers. It tracks velocity, code quality, review patterns, and delivery risk. Connects to GitHub in 5 minutes with read-only access. No source code is stored. [Learn more](https://codepulsehq.com) | [Try free](https://codepulsehq.com/login)
[Read the full article](https://codepulsehq.com/guides/analytics-as-code-guide)